# GLPN
这是一个近期推出的模型,因此其 API 尚未经过充分测试。未来可能需要修复一些 bug 或轻微的破坏性变更。如果您发现任何异常,请提交一个 [Github Issue](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title)。
## 概述
GLPN 模型由 Doyeon Kim、Woonghyun Ga、Pyungwhan Ahn、Donggyu Joo、Sehwan Chun 和 Junmo Kim 在 [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) 中提出。GLPN 将 [SegFormer](segformer) 的层级混合 Transformer 与一个轻量级解码器相结合,用于单目深度估计。所提出的解码器在计算复杂度显著降低的情况下,表现出优于先前提出的解码器的性能。
该论文的摘要如下:
*从单张图像进行深度估计是一项重要的任务,可应用于计算机视觉的多个领域,并随着卷积神经网络的发展而迅速兴起。本文提出了一种新颖的架构和训练策略,用于单目深度估计,以进一步提升网络的预测精度。我们部署了一个分层 Transformer 编码器来捕获并传递全局上下文,并设计了一个轻量级但功能强大的解码器,在考虑局部连通性的同时生成估计的深度图。通过我们提出的选择性特征融合模块,在多尺度局部特征与全局解码流之间构建连接路径,网络能够整合这两种表示并恢复精细细节。此外,所提出的解码器在计算复杂度显著降低的情况下,表现出优于先前提出的解码器的性能。此外,我们利用深度估计中的一个重要观察结果来改进深度特定的数据增强方法,从而增强模型。我们的网络在具有挑战性的深度数据集 NYU Depth V2 上达到了最先进的性能。我们进行了大量实验来验证并展示所提出方法的有效性。最后,与其他对比模型相比,我们的模型表现出更好的泛化能力和鲁棒性。*
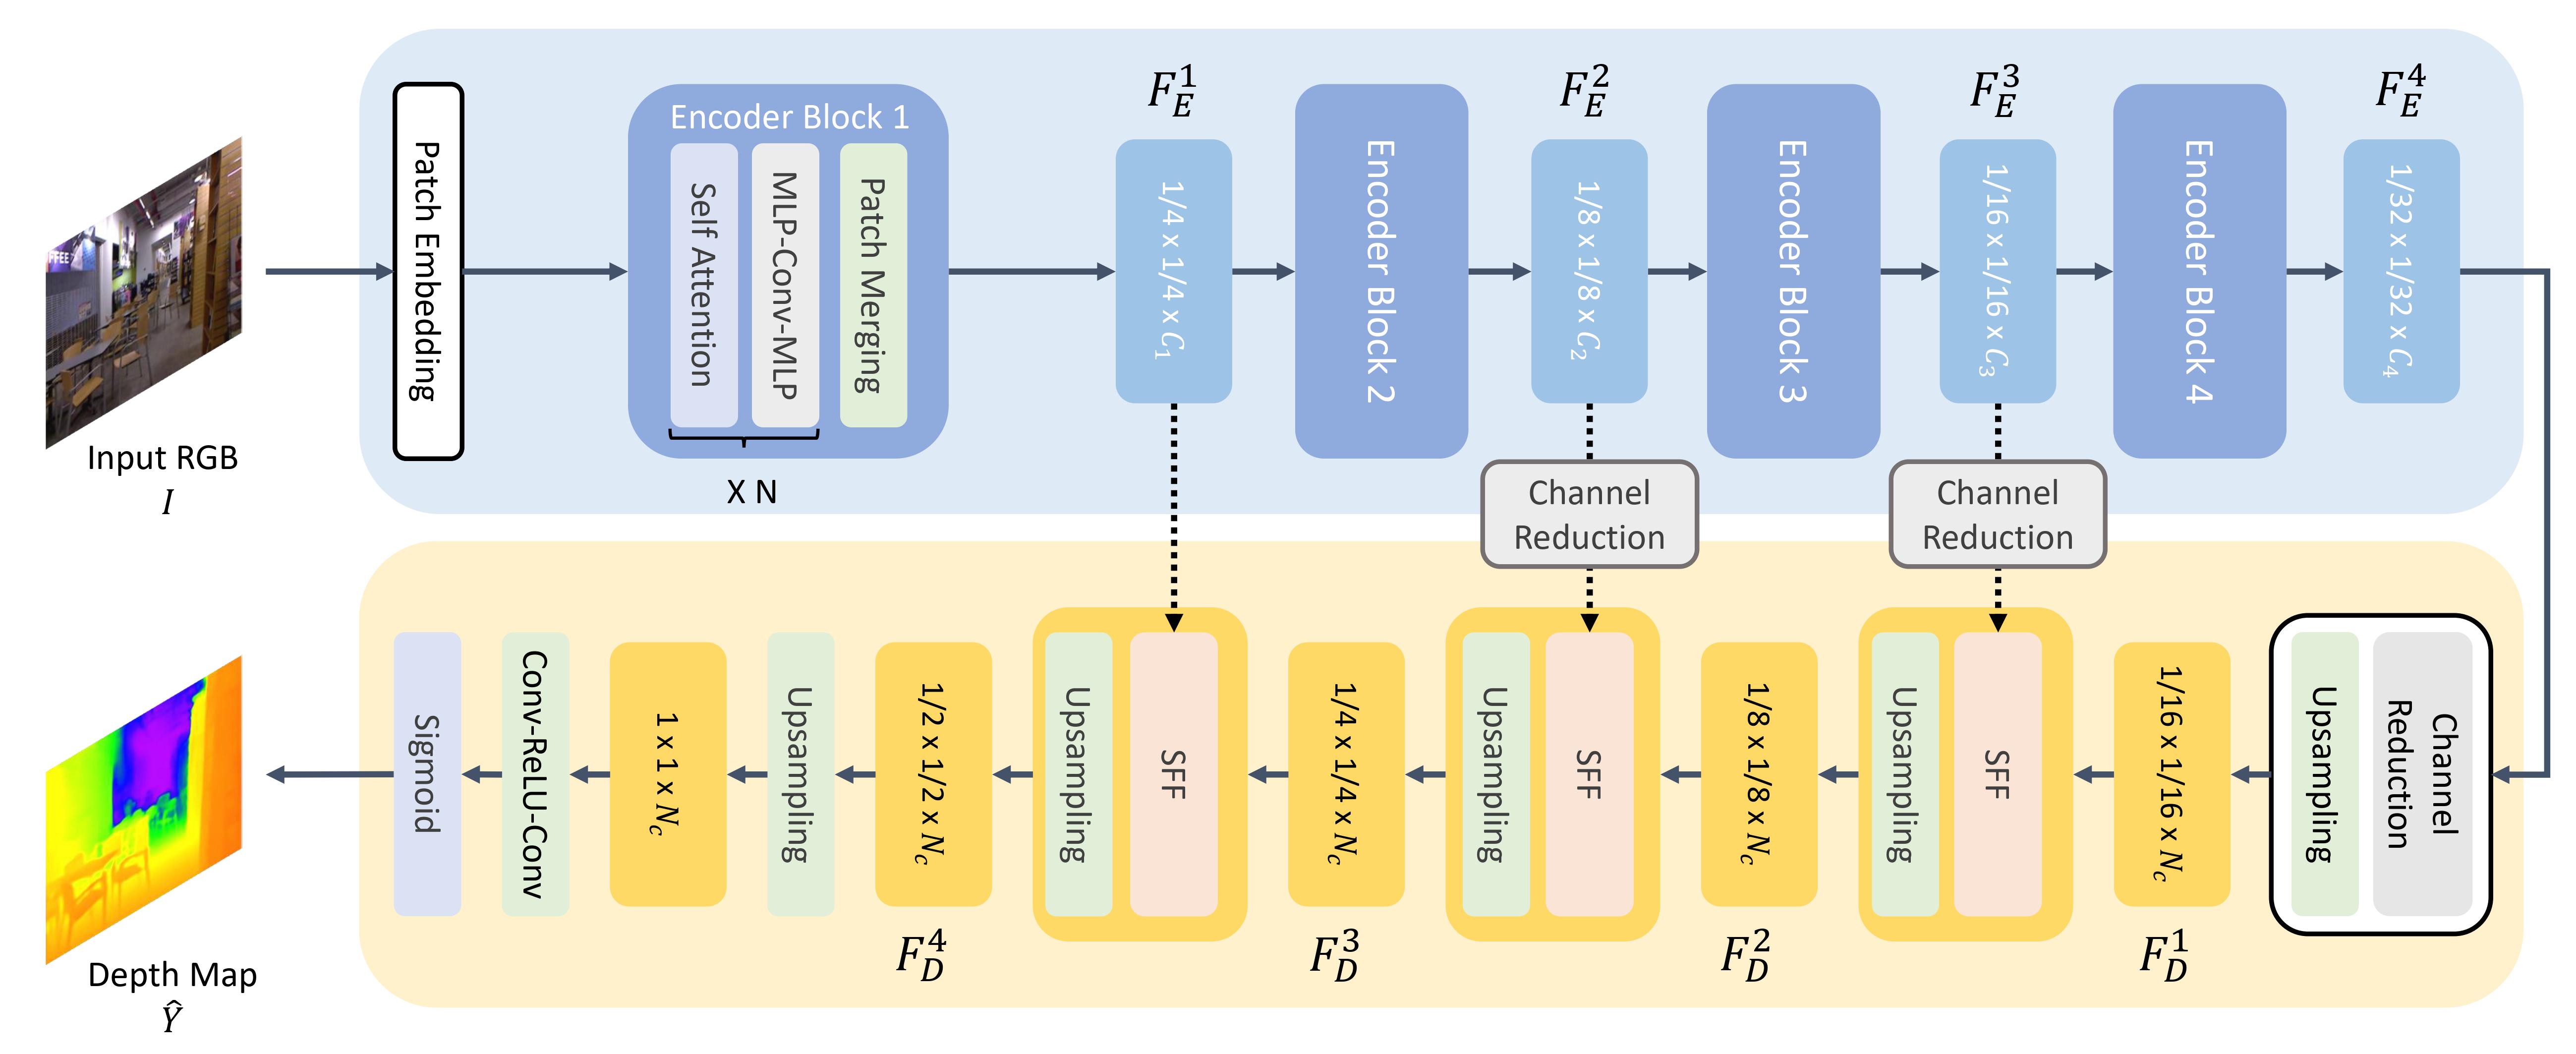 方法概述。摘自原始论文。
该模型由 [nielsr](https://huggingface.co/nielsr) 贡献。原始代码可在[此处](https://github.com/vinvino02/GLPDepth)找到。
## 资源
一份来自 Hugging Face 官方和社区(以 🌎 标识)的资源列表,帮助你开始使用 GLPN。
- [GLPNForDepthEstimation](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNForDepthEstimation) 的演示笔记本可在[此处](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GLPN)找到。
- [单目深度估计任务指南](../tasks/monocular_depth_estimation)
## GLPNConfig[[transformers.GLPNConfig]]
#### transformers.GLPNConfig[[transformers.GLPNConfig]]
```python
transformers.GLPNConfig(transformers_version: str | None = None, architectures: list[str] | None = None, output_hidden_states: bool | None = False, return_dict: bool | None = True, dtype: str | torch.dtype | None = None, chunk_size_feed_forward: int = 0, is_encoder_decoder: bool = False, id2label: dict[int, str] | dict[str, str] | None = None, label2id: dict[str, int] | dict[str, str] | None = None, problem_type: Literal['regression', 'single_label_classification', 'multi_label_classification'] | None = None, num_channels: int = 3, num_encoder_blocks: int = 4, depths: list[int] | tuple[int, ...] = (2, 2, 2, 2), sr_ratios: list[int] | tuple[int, ...] = (8, 4, 2, 1), hidden_sizes: list[int] | tuple[int, ...] = (32, 64, 160, 256), patch_sizes: list[int] | tuple[int, ...] = (7, 3, 3, 3), strides: list[int] | tuple[int, ...] = (4, 2, 2, 2), num_attention_heads: list[int] | tuple[int, ...] = (1, 2, 5, 8), mlp_ratios: list[int] | tuple[int, ...] = (4, 4, 4, 4), hidden_act: str = 'gelu', hidden_dropout_prob: float | int = 0.0, attention_probs_dropout_prob: float | int = 0.0, initializer_range: float = 0.02, drop_path_rate: float | int = 0.1, layer_norm_eps: float = 1e-06, decoder_hidden_size: int = 64, max_depth: int = 10, head_in_index: int = -1)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/configuration_glpn.py#L24)
**参数:**
num_channels (`int`,*可选*,默认为 `3`):输入通道数。
num_encoder_blocks (`int`, *可选*,默认为 4):编码器块的数量(即 Mix Transformer 编码器中的阶段数)。
depths (`list[int]`,*可选*,默认为 `[2, 2, 2, 2]`):每个编码器块中的层数。
sr_ratios (`list[int]`,*可选*,默认为 `[8, 4, 2, 1]`):每个编码器块中的序列缩减比例。
hidden_sizes (`Union[list[int], tuple[int, ...]]`,*可选*,默认为 `(32, 64, 160, 256)`):模型每个阶段的维度(隐藏层大小)。
patch_sizes (`list[int]`,*可选*,默认为 `[7, 3, 3, 3]`):每个编码器块之前的补丁大小。
strides (`list[int]`,*可选*,默认为 `[4, 2, 2, 2]`):每个编码器块之前的步长。
num_attention_heads (`list[int]`,*可选*,默认为 `[1, 2, 5, 8]`):Transformer 编码器中每个块内每个注意力层的注意力头数量。
mlp_ratios (`list[int]`,*可选*,默认为 `[4, 4, 4, 4]`):编码器块中 Mix FFN 的隐藏层大小与输入层大小的比例。
hidden_act (`str`,*可选*,默认为 `gelu`):解码器中的非线性激活函数(函数或字符串)。例如,`"gelu"`、`"relu"`、`"silu"` 等。
hidden_dropout_prob (`Union[float, int]`,*可选*,默认值为 `0.0`):嵌入层、编码器和池化器中所有全连接层的 dropout 概率。
attention_probs_dropout_prob (`Union[float, int]`,*可选*,默认值为 `0.0`):注意力概率的 dropout 比率。
initializer_range (`float`,*可选*,默认值为 `0.02`):用于初始化所有权重矩阵的 truncated_normal_initializer 的标准差。
drop_path_rate (`Union[float, int]`,*可选*,默认为 `0.1`):用于 patch 融合的 drop path 比率。
layer_norm_eps (`float`, *可选*, 默认为 `1e-06`) : 层归一化层使用的 epsilon。
decoder_hidden_size (`int`,*可选*,默认为 64):解码器的维度。
max_depth (`int`,*可选*,默认为 10):解码器的最大深度。
head_in_index (`int`,*可选*,默认为 -1):在 head 中使用的特征索引。
这是用于存储 GLPNModel 配置的类。它根据指定的参数实例化 Glpn 模型,并定义模型架构。使用默认值实例化配置将得到与 [vinvino02/glpn-kitti](https://huggingface.co/vinvino02/glpn-kitti) 类似的配置
配置对象继承自 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig),可用于控制模型输出。有关更多信息,请参阅 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig) 的文档。
示例:
```python
>>> from transformers import GLPNModel, GLPNConfig
>>> # Initializing a GLPN vinvino02/glpn-kitti style configuration
>>> configuration = GLPNConfig()
>>> # Initializing a model from the vinvino02/glpn-kitti style configuration
>>> model = GLPNModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
## GLPNImageProcessor[[transformers.GLPNImageProcessor]]
#### transformers.GLPNImageProcessor[[transformers.GLPNImageProcessor]]
```python
transformers.GLPNImageProcessor(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/image_processing_glpn.py#L51)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`,*kwargs*,*可选*,默认为 `True`):当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认为 `2`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
size_divisor (`int`, *kwargs*, *可选*,默认为 32) : 当 `do_resize` 为 `True` 时,图像会被调整大小,使其高度和宽度向下取整到 `size_divisor` 的最近倍数。
构建一个 GLPNImageProcessor 图像处理器。
#### preprocess[[transformers.GLPNImageProcessor.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/image_processing_glpn.py#L70)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
size_divisor (`int`, *kwargs*, *可选*,默认为 32) : 当 `do_resize` 为 `True` 时,图像会被调整大小,使其高度和宽度向下取整到 `size_divisor` 的最近倍数。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
## GLPNImageProcessorPil[[transformers.GLPNImageProcessorPil]]
#### transformers.GLPNImageProcessorPil[[transformers.GLPNImageProcessorPil]]
```python
transformers.GLPNImageProcessorPil(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/image_processing_pil_glpn.py#L46)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`,*kwargs*,*可选*,默认为 `True`):当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认为 `2`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
size_divisor (`int`, *kwargs*, *可选*,默认为 32) : 当 `do_resize` 为 `True` 时,图像会被调整大小,使其高度和宽度向下取整到 `size_divisor` 的最近倍数。
构建一个 GLPNImageProcessor 图像处理器。
#### preprocess[[transformers.GLPNImageProcessorPil.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/image_processing_pil_glpn.py#L65)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
size_divisor (`int`, *kwargs*, *可选*,默认为 32) : 当 `do_resize` 为 `True` 时,图像会被调整大小,使其高度和宽度向下取整到 `size_divisor` 的最近倍数。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
## GLPNModel[[transformers.GLPNModel]]
#### transformers.GLPNModel[[transformers.GLPNModel]]
```python
transformers.GLPNModel(config: GLPNConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/modeling_glpn.py#L377)
**参数:**
config ([GLPNConfig](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNConfig)):模型配置类,包含模型的所有参数。使用配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
未添加任何特定头部的裸 Glpn 模型,直接输出原始隐藏状态。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.GLPNModel.forward]]
```python
forward(pixel_values: Tensor, output_attentions: bool | None = None, output_hidden_states: bool | None = None, return_dict: bool | None = None, **kwargs)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/modeling_glpn.py#L389)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`):与输入图像对应的张量。可以使用 [GLPNImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNImageProcessor) 获取像素值。有关详细信息,请参阅 [GLPNImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [GLPNImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNImageProcessor) 处理图像)。
output_attentions (`bool`, *可选*) : 是否返回所有注意力层的注意力张量。有关更多详细信息,请参阅返回张量中的 `attentions`。
output_hidden_states (`bool`, *可选*) : 是否返回所有层的隐藏状态。有关更多详细信息,请参阅返回张量中的 `hidden_states`。
return_dict (`bool`, *可选*) : 是否返回 [ModelOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.utils.ModelOutput) 而不是普通元组。
**返回:** [BaseModelOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.BaseModelOutput) 或 `tuple(torch.Tensor)`
一个 [BaseModelOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.BaseModelOutput) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([GLPNConfig](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNConfig))和输入。
[GLPNModel](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNModel) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **last_hidden_state**(形状为 `(batch_size, sequence_length, hidden_size)` 的 `torch.Tensor`)-- 模型最后一层输出的隐藏状态序列。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层的输出,以及每一层的输出),形状为 `(batch_size, sequence_length, hidden_size)`。
模型在每一层输出处的隐藏状态,以及可选的初始嵌入输出。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
```
## GLPNForDepthEstimation[[transformers.GLPNForDepthEstimation]]
#### transformers.GLPNForDepthEstimation[[transformers.GLPNForDepthEstimation]]
```python
transformers.GLPNForDepthEstimation(config: GLPNConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/modeling_glpn.py#L565)
**参数:**
config ([GLPNConfig](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNConfig)):模型配置类,包含模型的所有参数。使用配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
GLPN 模型,顶部配备轻量级深度估计头,例如用于 KITTI、NYUv2。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.GLPNForDepthEstimation.forward]]
```python
forward(pixel_values: Tensor, labels: typing.Optional[torch.Tensor] = None, output_attentions: bool | None = None, output_hidden_states: bool | None = None, return_dict: bool | None = None, **kwargs)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/glpn/modeling_glpn.py#L576)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`):与输入图像对应的张量。可以使用 [GLPNImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNImageProcessor) 获取像素值。有关详细信息,请参阅 [GLPNImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [GLPNImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNImageProcessor) 处理图像)。
labels (`torch.Tensor`,形状为 `(batch_size, height, width)`,*可选*):用于计算损失的真实深度估计图。
output_attentions (`bool`, *可选*) : 是否返回所有注意力层的注意力张量。有关更多详细信息,请参阅返回张量中的 `attentions`。
output_hidden_states (`bool`, *可选*) : 是否返回所有层的隐藏状态。有关更多详细信息,请参阅返回张量中的 `hidden_states`。
return_dict (`bool`, *可选*) : 是否返回 [ModelOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.utils.ModelOutput) 而不是普通元组。
**返回:** [DepthEstimatorOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.DepthEstimatorOutput) 或 `tuple(torch.Tensor)`
一个 [DepthEstimatorOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.DepthEstimatorOutput) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([GLPNConfig](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNConfig))和输入。
[GLPNForDepthEstimation](/docs/transformers/v5.23.0/zh/model_doc/glpn#transformers.GLPNForDepthEstimation) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **loss** (`torch.Tensor`,形状为 `(1,)`,*可选*,当提供 `labels` 时返回) -- 分类损失(如果 config.num_labels==1,则为回归损失)。
- **predicted_depth**(形状为 `(batch_size, height, width)` 的 `torch.Tensor`)-- 每个像素的预测深度。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个层输出的一个张量),形状为 `(batch_size, num_channels, height, width)`。
模型在每一层输出处的隐藏状态,以及可选的初始嵌入输出。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, patch_size, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
>>> from transformers import AutoImageProcessor, GLPNForDepthEstimation
>>> import torch
>>> import numpy as np
>>> from PIL import Image
>>> from huggingface_hub.utils import httpx
>>> from io import BytesIO
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> with httpx.stream("GET", url) as response:
... image = Image.open(BytesIO(response.read()))
>>> image_processor = AutoImageProcessor.from_pretrained("vinvino02/glpn-kitti")
>>> model = GLPNForDepthEstimation.from_pretrained("vinvino02/glpn-kitti")
>>> # prepare image for the model
>>> inputs = image_processor(images=image, return_tensors="pt")
>>> with torch.no_grad():
... outputs = model(**inputs)
>>> # interpolate to original size
>>> post_processed_output = image_processor.post_process_depth_estimation(
... outputs,
... target_sizes=[(image.height, image.width)],
... )
>>> # visualize the prediction
>>> predicted_depth = post_processed_output[0]["predicted_depth"]
>>> depth = predicted_depth * 255 / predicted_depth.max()
>>> depth = depth.detach().cpu().numpy()
>>> depth = Image.fromarray(depth.astype("uint8"))
```